Bigger chatbots, worse at saying 'I don't know'
Ourtake
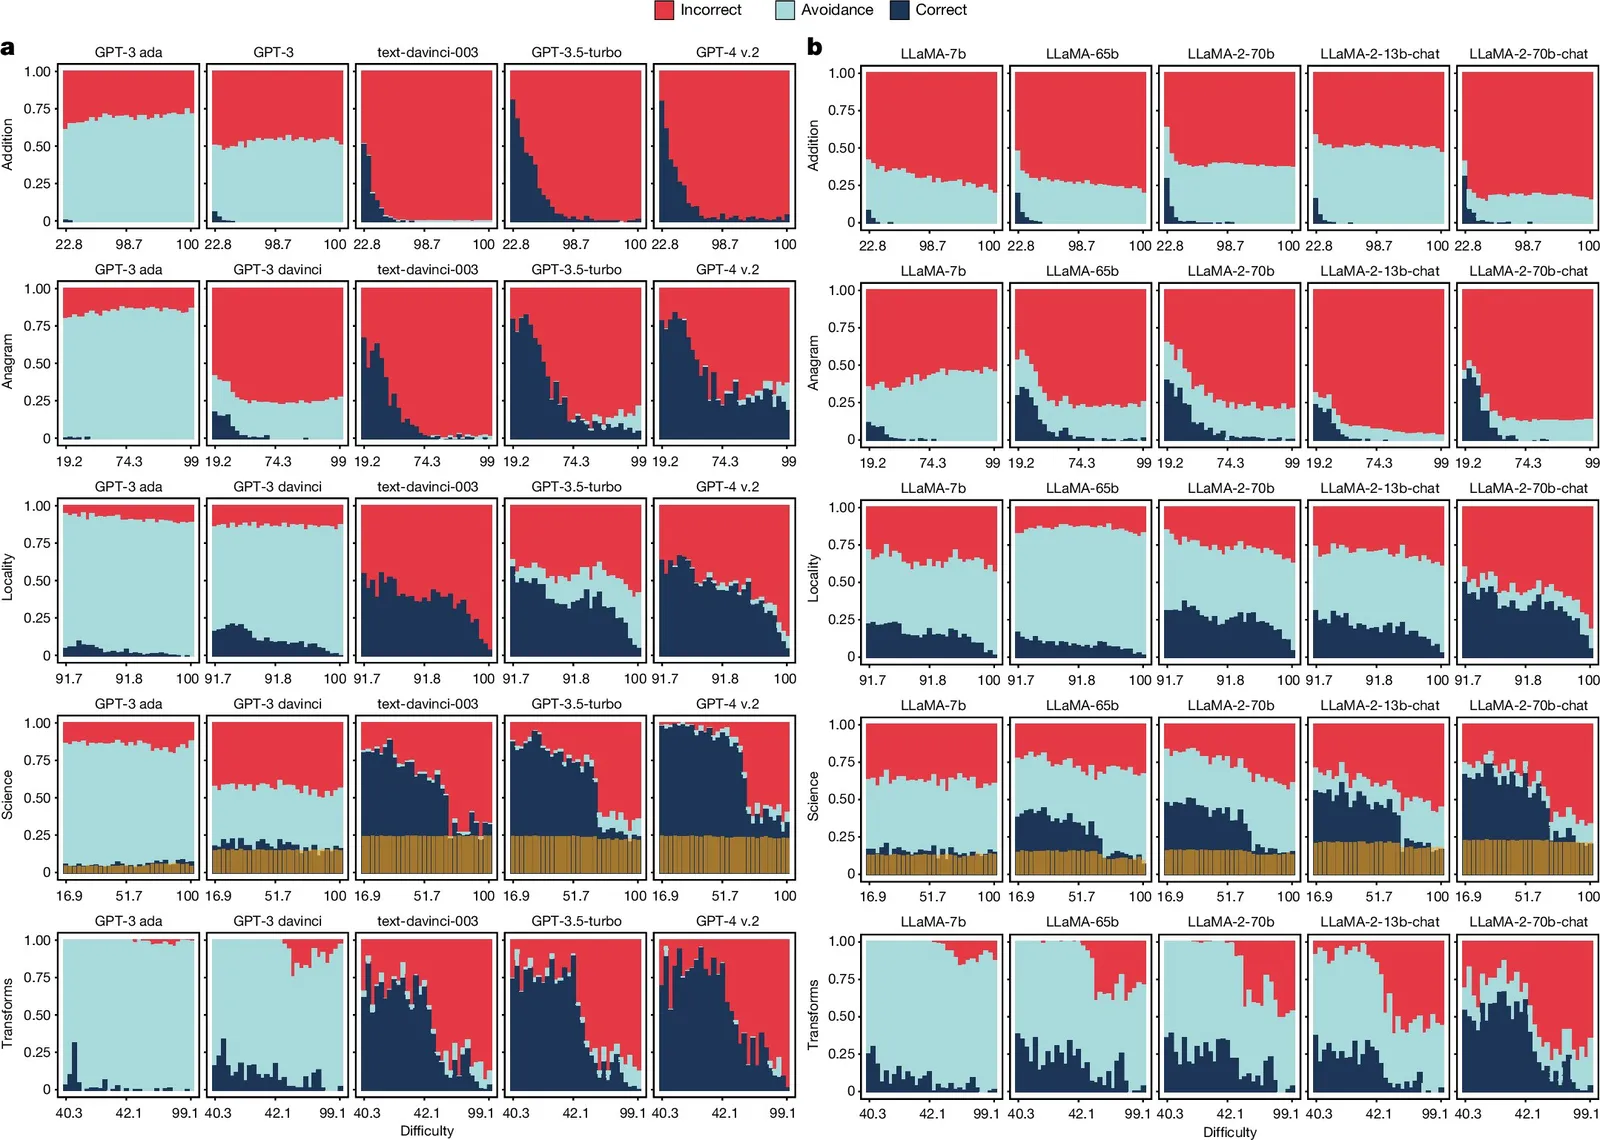
Scaling up made them more accurate on easy questions, but far more willing to bluff on hard ones.
What happened
Researchers at Universitat Politècnica de València tested BLOOM, LLaMA and GPT models across thousands of questions, published in Nature. Newer, larger versions were more likely to guess rather than admit ignorance, producing more incorrect answers, including on easy questions. Volunteers also struggled to spot the wrong answers.
Sources
- techxplore.com · As LLMs grow bigger, they're more likely to give wrong answers than admit ignorance (opens in a new tab)
- Futurism · The Most Sophisticated AIs Are Most Likely to Lie, Worrying Research Finds (opens in a new tab)
- nature.com · Bigger AI chatbots more inclined to spew nonsense — and people don’t always realize (opens in a new tab)